> ## Documentation Index
> Fetch the complete documentation index at: https://mintlify.com/mlfoundations/open_clip/llms.txt
> Use this file to discover all available pages before exploring further.
# Introduction
> OpenCLIP is an open-source implementation of OpenAI's CLIP (Contrastive Language-Image Pre-training) for training and using vision-language models.
# OpenCLIP
Welcome to OpenCLIP, an open-source implementation of OpenAI's [CLIP](https://arxiv.org/abs/2103.00020) (Contrastive Language-Image Pre-training). This codebase provides production-ready models for zero-shot image classification, image-text retrieval, and transfer learning tasks.
OpenCLIP is actively maintained by researchers at UW, Google, Stanford, Amazon, Columbia, and Berkeley, with continuous contributions from the open-source community.
## What is CLIP?
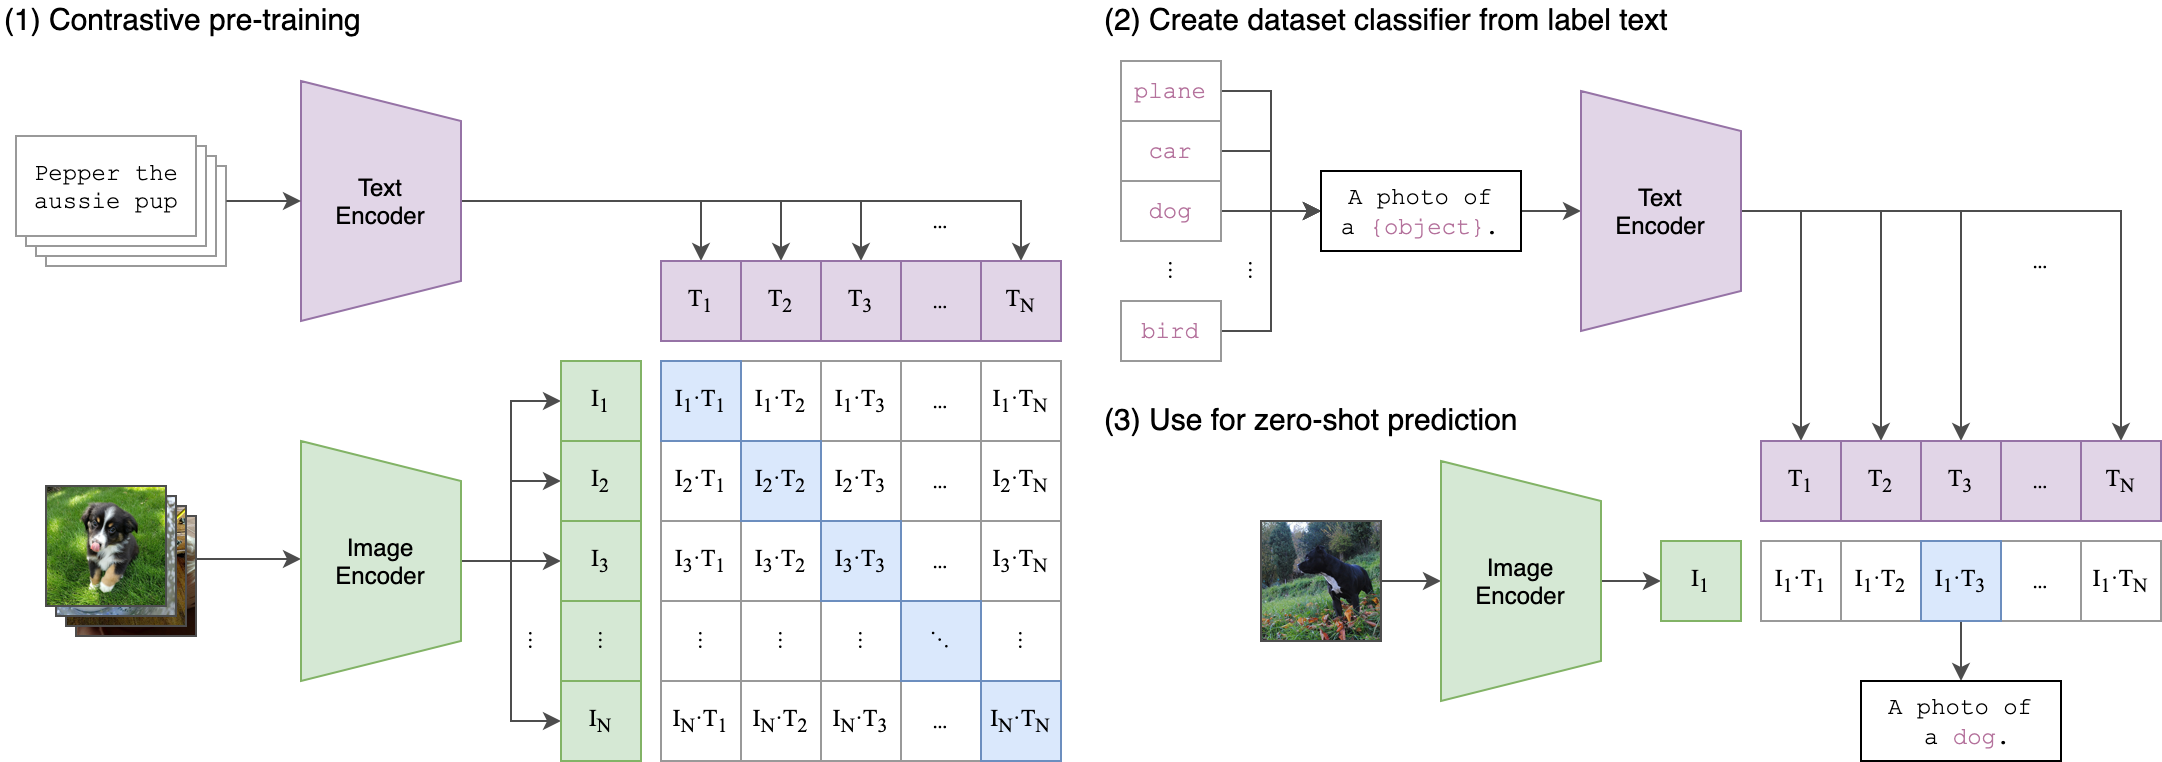
CLIP learns visual concepts from natural language supervision by training on image-text pairs. This approach enables powerful zero-shot transfer capabilities, allowing models to classify images into categories they've never explicitly seen during training.
 ## Key Features
OpenCLIP provides a comprehensive collection of pretrained models trained on various datasets including LAION-400M, LAION-2B, and DataComp-1B. Models range from efficient mobile architectures to large-scale transformers achieving up to 85.4% zero-shot accuracy on ImageNet.
Battle-tested on up to 1024 A100 GPUs with native support for SLURM clusters. Includes optimizations like gradient accumulation, local loss computation, and efficient memory management for large-scale training.
Perform image classification without training examples. Simply describe the classes in natural language and the model can identify them in images.
* Vision Transformers (ViT-B, ViT-L, ViT-H, ViT-bigG)
* ConvNet architectures (ConvNext, ResNet)
* SigLIP models for improved efficiency
* CoCa models for generative captioning
Clean, well-documented Python API with support for:
* Loading models from Hugging Face Hub
* Custom preprocessing pipelines
* Mixed precision training (FP16, BF16)
* JIT compilation
* WebDataset for large-scale datasets
## State-of-the-Art Results
OpenCLIP models achieve competitive or superior performance compared to proprietary alternatives:
| Model | Training Data | Resolution | ImageNet Zero-Shot Acc. |
| ---------------- | ------------- | ---------- | ----------------------- |
| ViT-bigG-14 | LAION-2B | 224px | 80.1% |
| ViT-L-14 | DataComp-1B | 224px | 79.2% |
| ConvNext-XXLarge | LAION-2B | 256px | 79.5% |
| ViT-H-14 | LAION-2B | 224px | 78.0% |
View the complete model zoo and zero-shot results across 38 datasets in our [model documentation](https://github.com/mlfoundations/open_clip/blob/main/docs/PRETRAINED.md).
## Research Foundation
OpenCLIP is backed by rigorous research on reproducible scaling laws for contrastive language-image learning:
**Paper**: [Reproducible Scaling Laws for Contrastive Language-Image Learning](https://arxiv.org/abs/2212.07143)\
Published at CVPR 2023
The research demonstrates how model performance scales with:
* Training compute budget
* Dataset size and quality
* Model architecture choices
* Training hyperparameters
## Use Cases
OpenCLIP powers a wide range of applications:
* **Zero-Shot Classification**: Classify images without training data
* **Image-Text Retrieval**: Search images using natural language queries
* **Transfer Learning**: Fine-tune on downstream tasks with robust pretrained features
* **Embedding Generation**: Create semantic embeddings for images and text
* **Content Moderation**: Filter and classify visual content
* **Multimodal Search**: Build search engines that understand both images and text
* **Data Curation**: Automatically label and organize image datasets
## Model Availability
All models are available through multiple channels:
* PyPI package: `open_clip_torch`
* Hugging Face Hub: [OpenCLIP library tag](https://huggingface.co/models?library=open_clip)
* Direct download from model zoo
Model cards with additional details are available on Hugging Face Hub.
## Community and Support
OpenCLIP is an active open-source project:
* GitHub: [mlfoundations/open\_clip](https://github.com/mlfoundations/open_clip)
* Issues and feature requests welcome
* Contributions from the community encouraged
Portions of the modeling and tokenizer code are adaptations of OpenAI's official [CLIP repository](https://github.com/openai/CLIP).
## Next Steps
Get started by installing the package via pip
Run your first zero-shot classification example
Browse the pretrained model zoo
Learn how to train CLIP on your own data